Overview
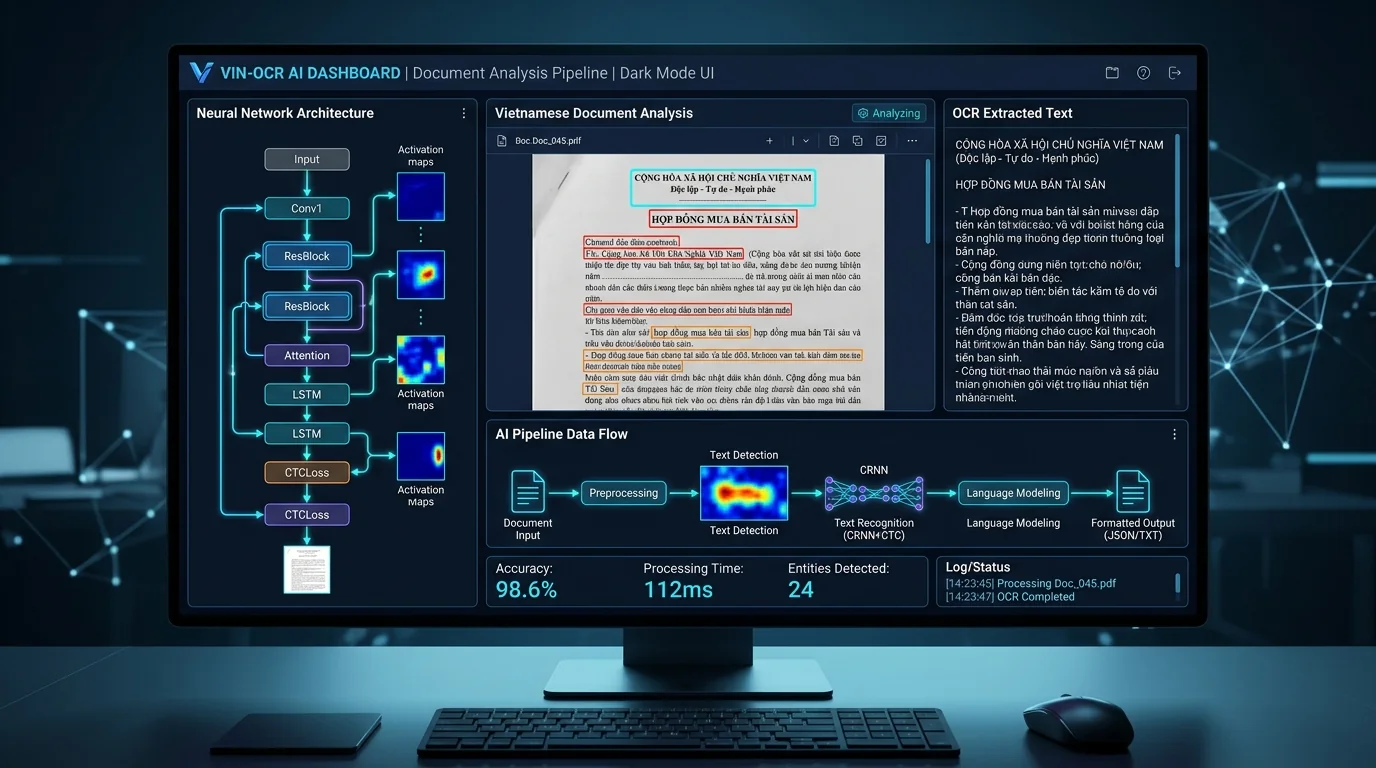
Deep Learning project covering two core domains: (1) Theoretical analysis & empirical simulation of Attention in LLMs (Self-Attention, block-wise FlashAttention, Linear Attention, Sparse Attention); (2) End-to-end Vietnamese Scene Text Recognition (OCR) pipeline on the MCOCR benchmark dataset.
System Architecture
Hybrid CNN + Transformer Decoder architecture: ResNet34 CNN backbone extracts visual spatial feature maps, a Spatial Attention module accentuates textual regions, and a Transformer Decoder autoregressively generates text sequences using Teacher Forcing with <start>, <end>, <pad>, and <unk> tokens.
Data & Database
MCOCR dataset: Images resized to (32, 128) with data augmentations (Random Rotation, Color Jitter); character-level vocabulary encoding preserving all Vietnamese diacritics and accented tone variations.
Key Challenges & Technical Solutions
- 01
1. Simulating & Benchmarking Attention Formulations:
Implemented Self-Attention, simplified FlashAttention (block-wise tile processing minimizing GPU memory overhead), and Linear Attention reducing sequence complexity from O(n²) to O(n).
- 02
2. Complex Vietnamese Diacritic Representation via Spatial Attention:
Augmented ResNet34 with Spatial Attention focusing on subtle tone markers; designed a comprehensive character-level vocabulary accommodating all accented variations.
- 03
3. Sequence Generation & Objective Evaluation via BLEU:
Employed Teacher Forcing for stable Transformer Decoder convergence, benchmarking character sequence predictions using BLEU scores against ground-truth text.