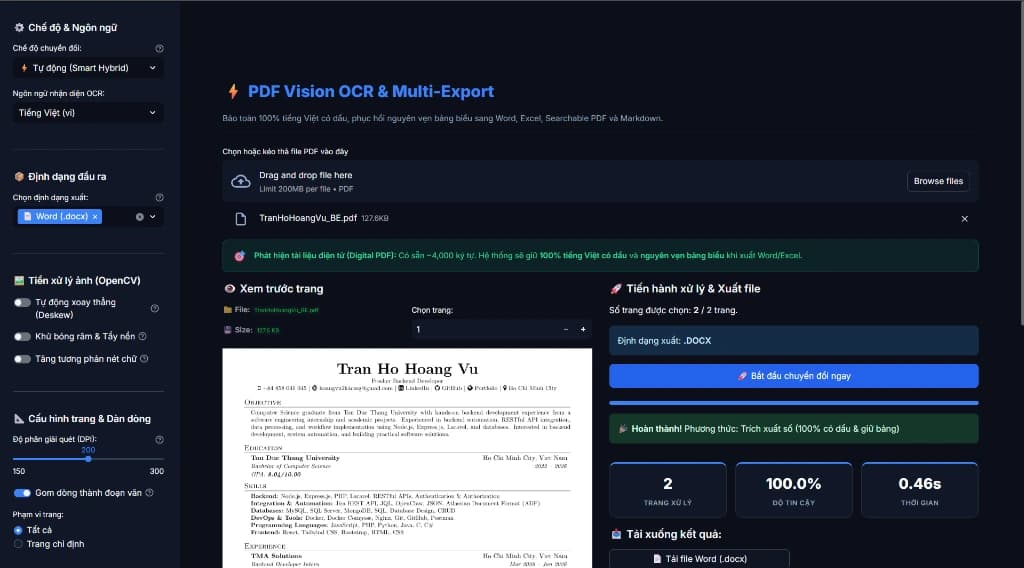
Overview
PDF Vision OCR is an intelligent optical character recognition system engineered for Vietnamese documents across scanned PDFs, mobile photo captures, and digital files. Preserves 100% Vietnamese diacritics and complex tabular layouts, offering multi-format export (DOCX, XLSX, Searchable PDF, Markdown, Master ZIP) with dual Streamlit Web UI and enterprise FastAPI REST API.
System Architecture
Modular architecture separating Image Preprocessing, OCR Engine Orchestration, Exporters, and Dual Delivery. Leverages in-memory PyMuPDF rendering eliminating external Poppler dependencies for lightweight Docker deployments.
Data & Database
OpenCV image processing pipeline: Auto-Deskew alignment via Hough Lines / minAreaRect, morphological shadow removal, and CLAHE adaptive local contrast enhancement.
Key Challenges & Technical Solutions
- 01
1. Preserving Vietnamese Diacritics & Tabular Structural Integrity:
Auto-detects native text layers in digital PDFs; for scanned documents, combines Vietnamese-trained PaddleOCR with bounding box coordinate clustering to reconstruct table layouts in DOCX and XLSX.
- 02
2. Low-Quality Scans & Handwritten Document Extraction:
Integrated Google Gemini 2.5 Flash Vision API via structured prompting with automatic graceful fallback to local PaddleOCR during offline or quota events.
- 03
3. Dual-Interface Deployment & Multi-Mode Containerization:
Designed a multi-purpose Docker container dynamically managed by APP_MODE environment variables (web, api, full) and Docker Compose profiles.